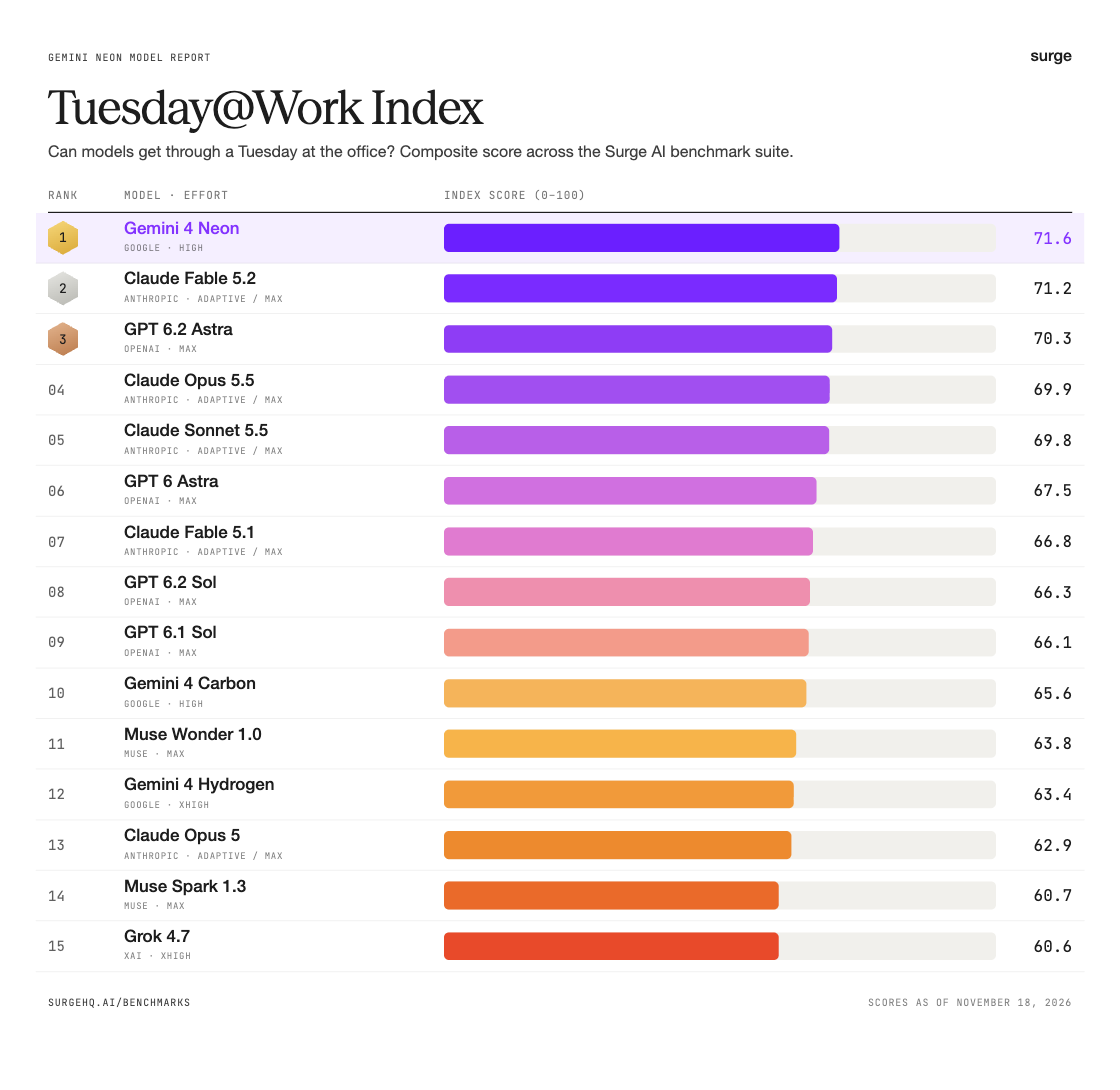
Gemini 4 Neon takes the #1 spot on Surge AI's Tuesday@Work Index, scoring 71.6 and narrowly edging out Claude Fable 5.2 (71.2).
Across Surge AI's broader benchmark suite, Neon delivers particularly strong results on professional knowledge work, though its performance varies significantly by domain.
Gemini 4 Neon across Surge's benchmark suite
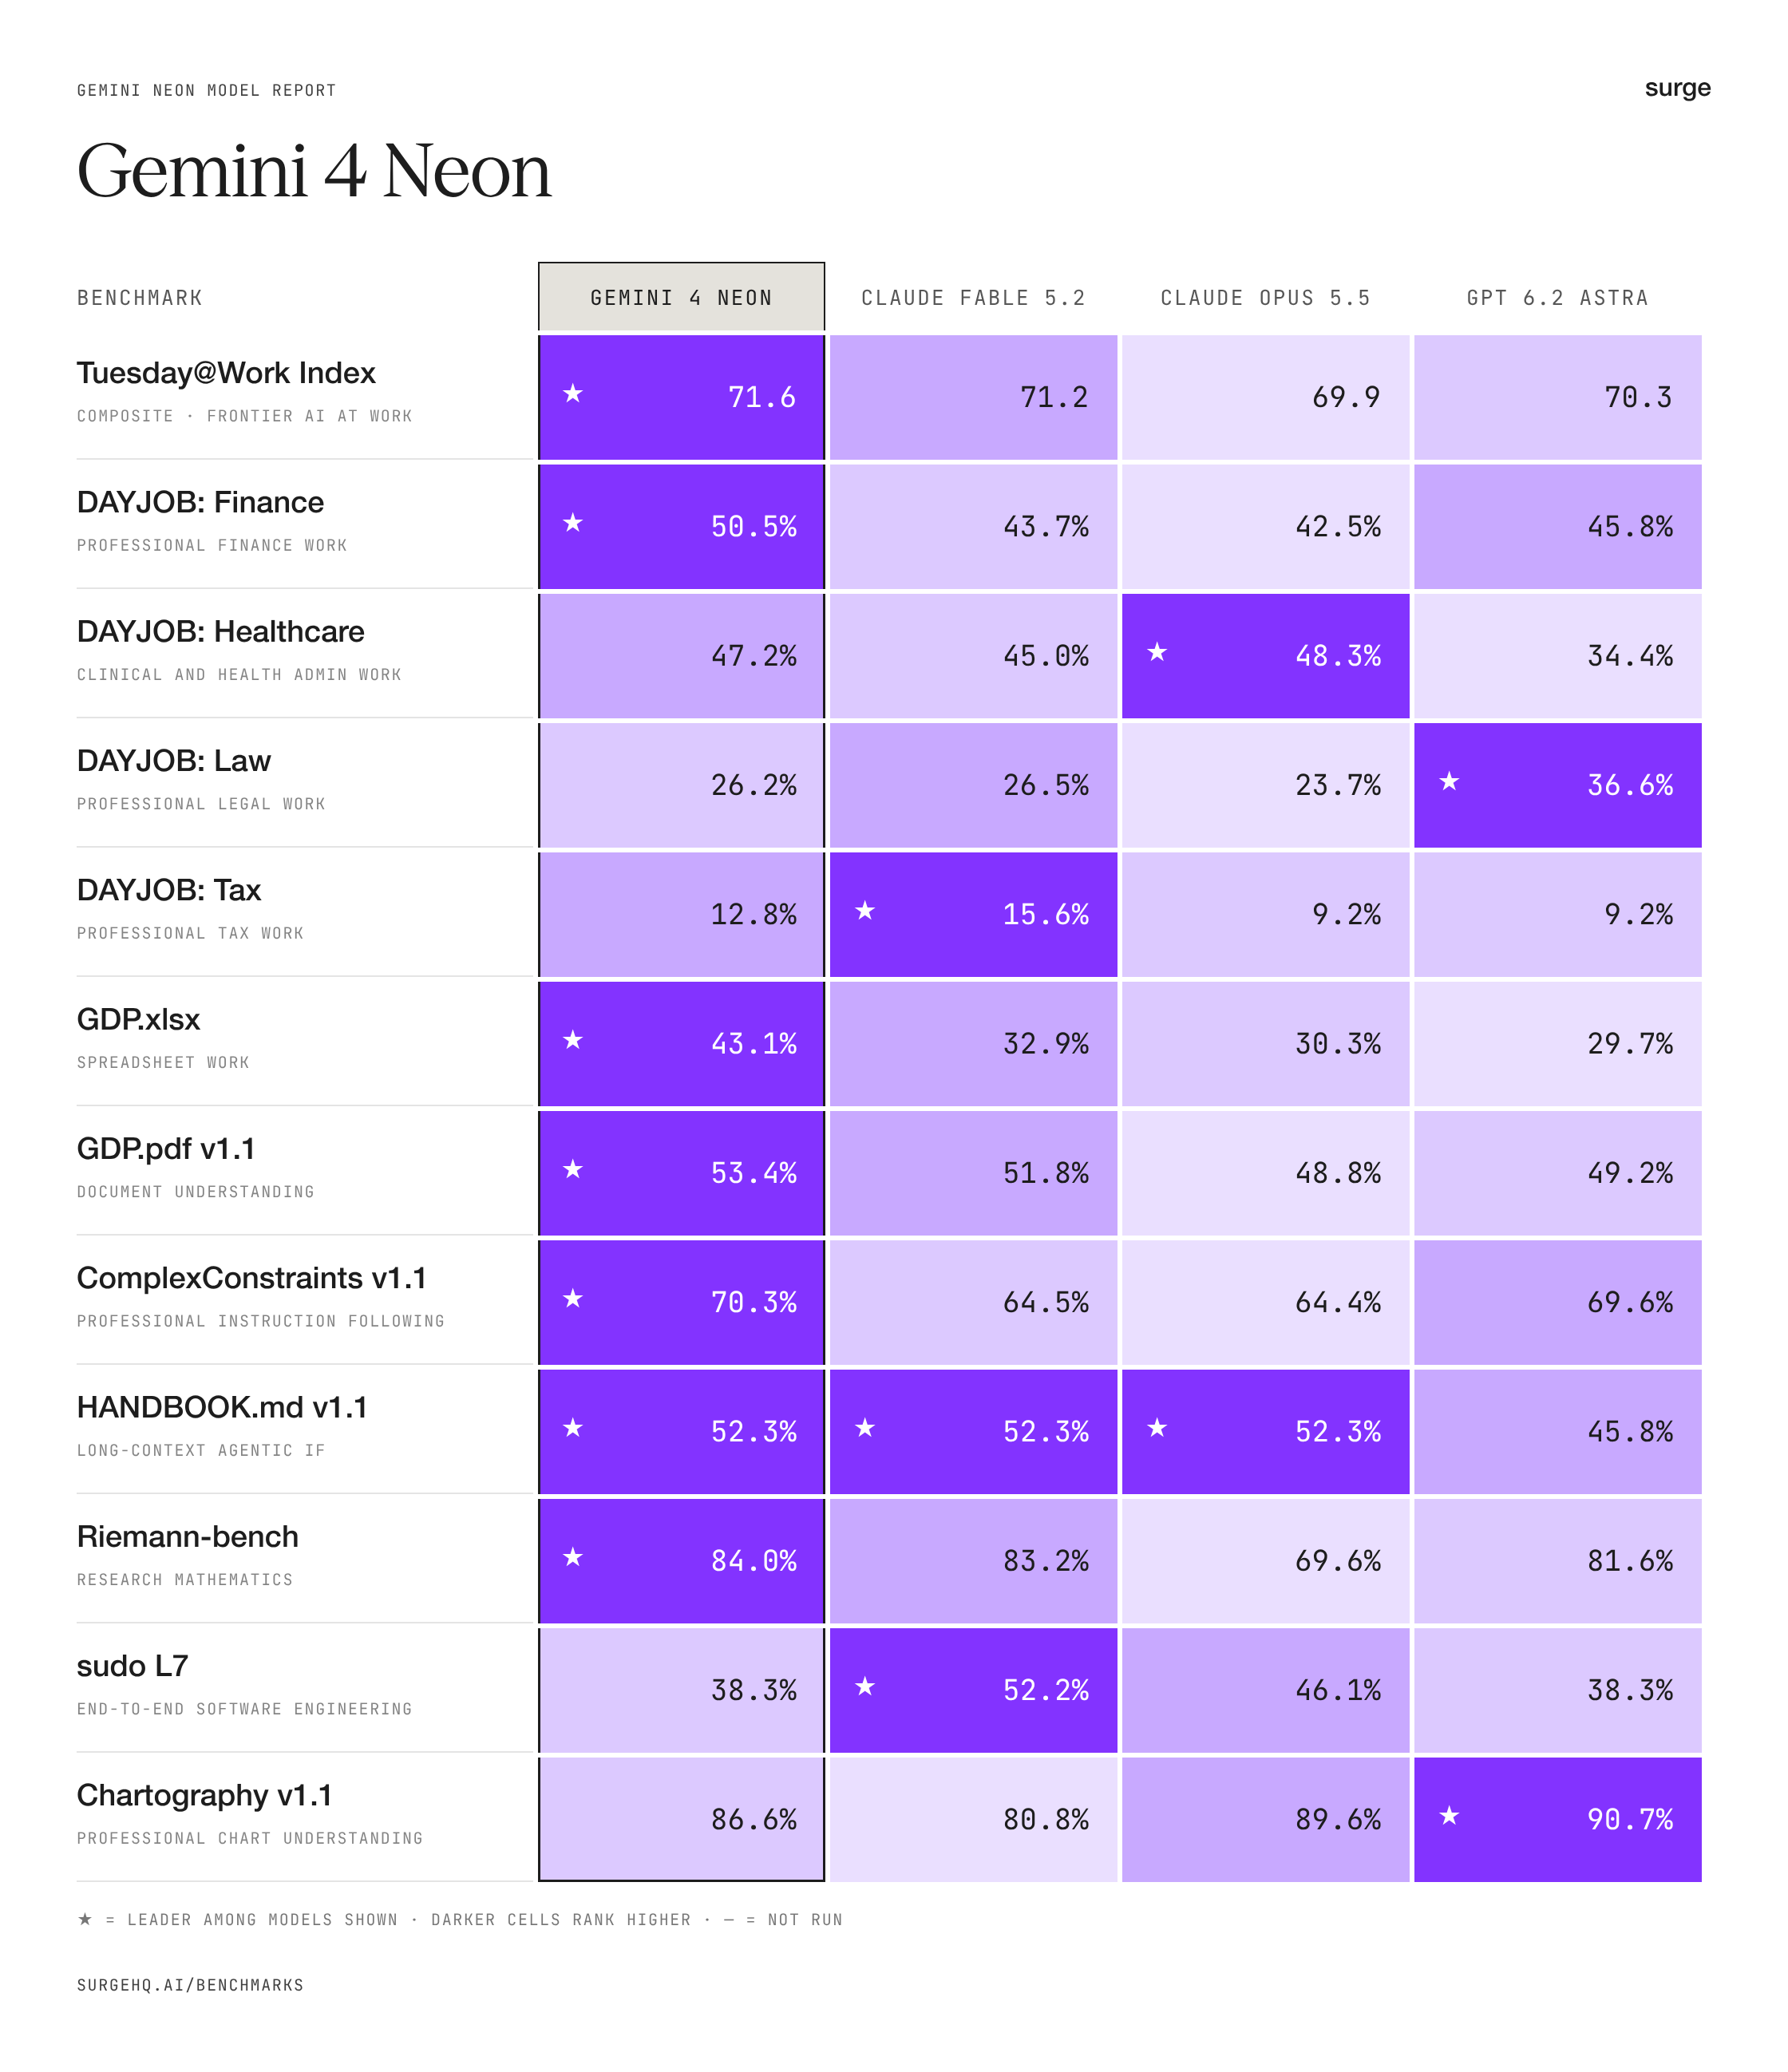
Neon’s strongest results come from professional knowledge work: finance, spreadsheets, long-context instruction following, and advanced mathematics.
Its weaker relative performances come on DAYJOB: Law, where it ranks seventh, and Chartography, where it ranks sixth. These benchmarks test distinct capabilities, professional legal work and enterprise chart understanding, highlighting that Neon's overall lead doesn't translate into dominance across every task.
Neon beats Claude on Finance with one-third the output tokens
Neon takes the top spot on DAYJOB: Finance, outperforming Claude models while using substantially fewer tokens and tool calls.
DAYJOB: Finance covers 80 tasks, including credit memos, acquisition and valuation models, covenant tests, and stress tests. Neon scores 50.5%, ahead of GPT 6.2 Astra at 45.8% and Fable 5.2 at 43.7%.
The efficiency gap is even larger than the performance gap. On Finance, Neon generated 205,000 output tokens, compared with 644,000 for Fable.
Neon does more of the work correctly, with roughly one-third the tokens.
Neon leads on Spreadsheets and matches Claude on Agentic Instruction Following
Neon also performs well on two benchmarks that test essential capabilities for enterprise agents: working in complex spreadsheets and following interacting instructions.
GDP.xlsx evaluates whether agents can operate inside the spreadsheets businesses actually use. Neon scores 43.1%, taking the top spot.
HANDBOOK.md tests whether agents can follow 100-page company handbooks. Neon matches Fable 5.2 and Opus 5.5 at 52.3% (ranked third).
Where Neon falls behind
Despite its strong overall performance, Neon still has weaknesses.
Neon trails Claude in Staff Software Engineering
On sudo L7, our benchmark for end-to-end software engineering, Neon scores 38.3%, well behind Claude Fable 5.2 at 52.2%, Sonnet 5.5 at 50.6%, and Opus 5.5 at 46.1%.
Fable leads Neon across all eight engineering dimensions we evaluate. The largest gaps are in:
- Integrity: 89.7% for Fable vs. 75.7% for Neon
- Communication: 77.4% vs. 64.1%
- Common sense: 88.1% vs. 75.8%
Neon was also more likely to write tests that validated its own implementation rather than the underlying risk the task was designed to address.
Smaller gaps in Tax and Healthcare, a larger one in Law
Neon comes in second on two DAYJOB benchmarks and seventh on a third.
On DAYJOB: Tax, the hardest benchmark in the family, Neon scores 12.8%, compared with Fable 5.2’s 15.6%.
On DAYJOB: Law, Neon scores 26.2%, ranking seventh behind GPT 6 Astra at 36.6%.
On DAYJOB: Healthcare, Neon scores 47.2%, 1.1 points behind Claude Opus 5.5.
These gaps are narrower than the one on sudo L7, but they show that Neon’s strength in professional knowledge work isn’t universal.
A new leader, with a different set of tradeoffs
Gemini 4 Neon takes the top spot on the Tuesday@Work Index with a score of 71.6, setting a new high across our evaluations.
Its strengths are clear: finance, spreadsheets, and agentic instruction following, sometimes outperforming Claude while using a fraction of the output tokens.
But the behavioral differences are just as interesting as the leaderboard.
Neon is more decisive, more likely to preserve its reasoning in the final deliverable, and more faithful to client instructions. That decisiveness also makes it more prone to overstating what the evidence supports.
Claude remains substantially stronger at end-to-end software engineering, particularly when tasks require scope control, sound testing decisions, and engineering judgment.
Explore the full results on the Surge benchmarks page.